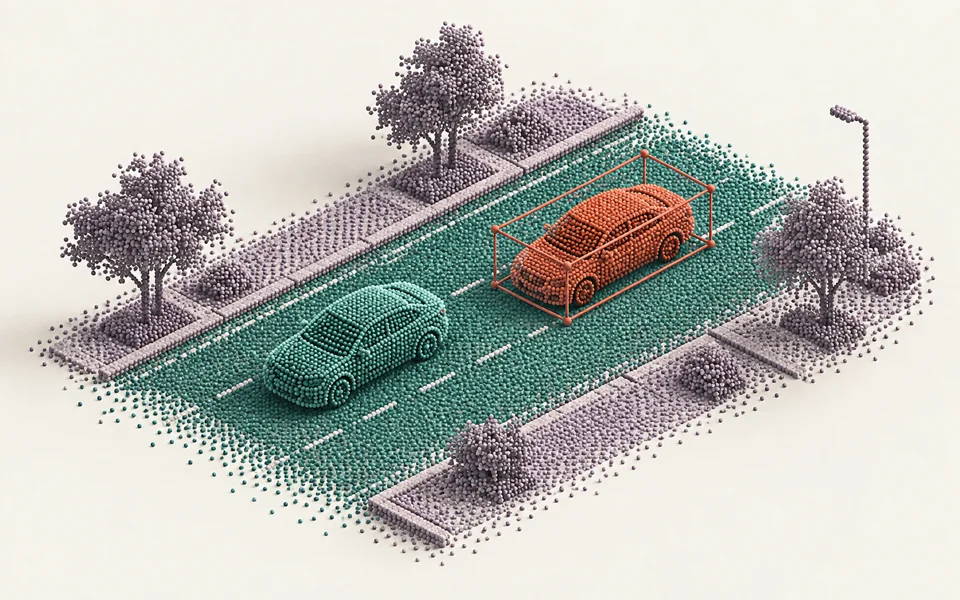
Label objects and regions in 3D.
Annotate 3D bounding boxes, semantic classes, and instances in point clouds, with linked camera views to help review the scene.
- 3D object detection
- Semantic and instance segmentation
- Linked camera views
Workflows
Annotate, review, and export point cloud, image, document, video, and multimodal data in one workspace, with model assistance when you need it.
Annotate 3D bounding boxes, semantic classes, and instances in point clouds, with linked camera views to help review the scene.

Build multiclass, multilabel, and hierarchical classification datasets without separating image-level decisions from shape-level review.

Parse text, tables, formulas, and document layouts with PaddleOCR, then inspect and correct every region in the same workspace.

Create and review labeled time segments, navigate long clips efficiently, and preserve the temporal context behind every classification.

Design repeatable question templates, combine manual and model-assisted answers, and export data for modern vision-language training.

Talk to a vision-language model with the current image in context, refine the response, and preserve approved conversations as training data.